> ## Documentation Index
> Fetch the complete documentation index at: https://docs.xpander.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Air-gapped deployment
> Every xpander component in your environment with no connection to xpander cloud at run time: license, registry mirroring, the installer flow, data tier options, and upgrades
## Overview
**Air-gapped** is the self-hosted deployment that runs every xpander component in your environment. **Nothing connects to xpander cloud at run time.** That scope covers the web UI, the control plane services, a self-hosted Supabase stack (auth, storage, edge functions), and the data tier (PostgreSQL, Redis Stack, MongoDB). It is one Helm release, in one namespace. Nothing is sent to xpander: no heartbeats, no catalog sync, no telemetry. Every other connection is optional and yours: your LLM endpoint, the cloud services you choose (Bedrock, S3, SES), and the registry you mirror from at install time. The install-time / run-time / never split is the egress table on [Air-Gapped Security Architecture](/resources/security-compliance/air-gapped-deployments#what-leaves-the-environment). Entitlement is a sealed, signed Ed25519 license verified in-cluster. As in every self-hosted edition, agents' skill calls, including skills served over MCP, run from your cluster, and agent workspaces (the agents' computers) run there too. MCP clients such as Claude, ChatGPT or Cursor can connect to Omni, the built-in agent, once the install sets its MCP origin, `global.mcp.publicUrl`. Until then, with `global.mcp.publicUrl` unset and `ui.env.VITE_OMNI_MCP_URL` empty, Settings > Channels lists MCP as not configured. It installs in a cloud VPC in private mode (no internet or NAT gateways), or in any disconnected compute environment.
Zero egress to xpander Cloud, signed Ed25519 license, local sign-in, and what stays in your environment. Diagrams live on that page. This guide does not repeat them.
Three things define an air-gapped install:
1. **The license is the identity.** Two sealed files (`install.json` and `activation.json`, the `xpander-license/v2` format) plus the organization id you pass with `--org`: there are **no console IDs and no API key**. Installs issued with the older single `license.json` (v1) carry the org id inside the file. The installer generates the environment id, and the first install's seed pipeline creates everything else in-cluster, including your organization. Single-tenant: the license binds one organization.
2. **Images come from your own registry mirror.** xpander delivers the artifact set through the gated `xpanderaihub` Docker Hub org with a per-customer read token; the installer mirrors it into a registry your cluster can reach, or you run the mirroring yourself on a sealed network.
3. **Image tags are pinned per release.** The chart refuses to render against unpinned images, and upgrades require mirroring the new bundle first.
The install runs through xpander's interactive installer wizard, invoked with `--edition airgap`. The flag selects the air-gap flow: a pre-install checklist, license validation, registry mirroring when needed, and a live watch over the chart's install pipeline.
"Air-gapped" means air-gapped **from xpander's cloud**, not necessarily from the internet. Internet-backed skills (web search, docs search, TTS) can stay enabled through the chart's internet-posture setting, or be sealed off entirely. Ask your xpander contact about the sealed hardening profile.
### What Talks to What
**Outbound (from your cluster).** Nothing to xpander is required at run time. The rows below are the connections you choose; the complete install-time / run-time / never table is on [Air-Gapped Security Architecture](/resources/security-compliance/air-gapped-deployments#what-leaves-the-environment).
| From your cluster | To | Purpose |
| - | - | - |
| LLM-serving components | Your LLM endpoint: in-network vLLM/Ollama/NIM, or Amazon Bedrock over a PrivateLink VPC endpoint, or a hosted provider if you allow it | Model calls |
| Skills (including MCP) | Only the external systems you choose to allow | Egress is your policy; the chart's internet-posture setting shapes which internet-backed skills are even offered |
| (install/upgrade time only) | xpander's registry, only when you use the [in-wizard mirroring](#when-the-mirror-is-empty-the-wizard-offers-to-fill-it) from a connected machine | Image delivery; a sealed network uses the [two-hop archive flow](#sealed--manual-mirroring) instead |
**Inbound (from your users to your cluster).** These are your network requirements for reaching xpander. All of them land on your ingress controller, over whatever path your network provides (internal DNS, VPN, private load balancer). The host names are the chart's derived defaults; every one is overridable per service, and [Domains, Ingress & DNS](#domains-ingress--dns) shows a reference customer's set and the URL knobs that move with a rename:
| From | To | Purpose |
| - | - | - |
| Users' browsers | `chat.`, `supabase.` | Using the web UI: invoking agents, chat, sign-in and file storage |
| SDK and API clients, CI pipelines | `api.`, `agent-controller.` | Invoking agents programmatically (REST, streaming, SDK) |
| In-network systems that trigger agents | `webhook.` | Webhook-triggered agent runs |
| OAuth redirect flows (browser) | `client-auth.` | Authorizing skills, [per-person MCP connector sign-in](/run/integrations/mcp-per-person-sign-in) and the SSO login callback |
| Users' browsers (optional) | The short-links origin (`global.shortLinks.publicUrl`) | Short links to signed attachments, served by the `functions` Service |
***
## Prerequisites
| Requirement | Value |
| - | - |
| Nodes | 3 × 8 vCPU / 32 GiB (e.g. `m5.2xlarge`), amd64. Larger installs: see [Sizing](/self-hosted/sizing#air-gapped) |
| Kubernetes | ≥ 1.28, with a working CNI and cluster DNS (CoreDNS), and a **CSI driver with a default RWO StorageClass**: xpander's stateful services provision PVCs through it. On EKS that means the `vpc-cni`, `coredns`, `kube-proxy`, and `aws-ebs-csi-driver` add-ons ([EKS Cluster Setup](/self-hosted/eks-setup#eks-add-ons)); on EKS Auto Mode the built-in `ebs.csi.eks.amazonaws.com` provisioner replaces that add-on ([EKS Auto Mode](/self-hosted/eks-setup#eks-auto-mode)); metrics-server is not required |
| Storage | \~700 GiB on an RWO StorageClass: **encrypted at rest** (the PVCs hold agent workspaces and customer data; on EKS: `encrypted: "true"` in the [StorageClass](/self-hosted/eks-setup#create-default-storageclass)) |
| Network | **No connection to xpander cloud at run time.** Every other connection is optional and yours (your LLM endpoint, cloud services, the registry you mirror from); the [egress table](/resources/security-compliance/air-gapped-deployments#what-leaves-the-environment) lists them. An LLM endpoint reachable in-network |
| License files | `install.json` and `activation.json` plus your organization id, issued by the xpander.ai team and delivered over email ([Two-File Licensing](/self-hosted/licensing)) |
| Container registry | Reachable by the cluster: the installer can fill it with the mirrored images for you |
| Optional | One GPU node (L4/A10 class) for voice / local inference |
| Tooling | `helm` ≥ 3.13 and `kubectl` on the machine you install from; `skopeo` + `python3` on whichever machine mirrors the images (Docker alone also works); `crane` or `skopeo` recommended for the installer's mirror verification |
To compare against the currently published requirements, see the chart's [requirements.json](https://charts.xpander.ai/requirements.json).
Agents run on Claude Code, Codex or OpenCode, on the executor fleet, which adds to these numbers and brings its own node prerequisites: privileged pods, cgroup v2, and XFS with `prjquota`. See [Sizing and requirements](/self-hosted/sizing). To run it without privileged containers, see [the unprivileged mode](/self-hosted/sizing#running-the-executor-fleet-without-privileged-containers).
The fleet (the pool of executor pods where agent turns run) is always rendered and starts warm with one executor. It has one storage prerequisite: a StorageClass that mounts XFS with `prjquota` for the 500 GiB per-executor volume. Bring that class under the name in `global.fleet.storage.className` (`fleet-xfs`; `createClass: false` is the Air-Gapped default). Or set `global.fleet.storage.createClass: true` on EKS to let the chart render the class for the EBS CSI driver (`ebs.csi.aws.com`, gp3, encrypted). On EKS Auto Mode also set `global.fleet.storage.provisioner: ebs.csi.eks.amazonaws.com`. The classic driver object exists there but has no controller behind it, so a class on `ebs.csi.aws.com` never binds. If that class is missing on a live cluster, or the driver named in `provisioner` is not installed, the chart renders the executor idle at `replicas: 0`, annotated `xpander.ai/fleet-idle-reason`. An `--atomic` install or upgrade then never waits on a volume that cannot bind. Create the class and the next upgrade brings the executor up.
Sizing tiers, the storage breakdown and how each service scales with usage are on [Sizing and requirements](/self-hosted/sizing#air-gapped).
***
## Install in Three Steps
The xpander.ai team issues and emails you: the **two sealed license files**, `install.json` (identity: org, edition, no expiry) and `activation.json` (entitlement: term, caps, features), your **organization id** for `--org`, the **license public key**, and **a registry pull token** for the gated `xpanderaihub` Docker Hub org (read-only, scoped to your account, individually revocable; it gates *delivery* only, the license is the enforcement). What each file gates and how renewal works: [Two-File Licensing](/self-hosted/licensing).
The license is the identity. Nothing else needs to be filled in up front:
```bash theme={"dark"}
curl -fsSL https://charts.xpander.ai/install.sh | bash -s -- \
--edition airgap --org \
--install-license-file ./install.json \
--activation-license-file ./activation.json
```
Legacy: an install issued with a single signed `license.json` (`xpander-license/v1`) passes `--license-file ./license.json` instead of the three flags above.
The command downloads the installer from `charts.xpander.ai` and runs an interactive wizard: preflight checks, configuration, Helm install, and a seeded admin login to sign in with when it finishes. Run it from a terminal with `kubectl` access to the target cluster.
The wizard prompts for the rest:
* Registry
* Chart source (OCI pull or local path)
* Data tier
* Admin email
* Organization display name
* StorageClass
* Whether to enable agent code execution (`--code-execution` / `--no-code-execution`). The runner embeds dockerd, so its pod must be privileged, and a restricted PodSecurity policy refuses it
* A [base domain](#domains-ingress--dns) for the public hosts
* LLM provider keys, for any hosted providers your egress policy allows
Image tags are not typed in: they are [read from the release](#releases).
**If your registry has no xpander images yet, the wizard detects it and offers to [mirror them right there](#when-the-mirror-is-empty-the-wizard-offers-to-fill-it)**: it asks for the pull token from step 1, copies every image with per-image progress, and creates ECR repositories automatically. On a sealed network, choose the runbook option instead and see [Sealed / manual mirroring](#sealed--manual-mirroring).
The first install's seed pipeline creates your organization and a bootstrap admin user in your own in-cluster Supabase. The closing summary prints the sign-in commands: see [Signing In](#signing-in).
A complete non-interactive invocation (image tags resolve from the mirror unless pinned):
```bash theme={"dark"}
bash install.sh --edition airgap \
--org --install-license-file ./install.json --activation-license-file ./activation.json \
--registry /xpander \
--chart-path xpander-airgap-.tgz \
--domain xpander.acme.internal \
--admin-email --org-name "" --yes
```
Prefer to see every command before anything runs? `bash install.sh --edition airgap --manual` prints the whole install as a personalized, copy-pasteable runbook and executes nothing: see [Advanced: review-first / manual install](/self-hosted/hybrid#advanced-review-first--manual-install).
***
## What Happens When You Run the Installer
The full anatomy of an install, in order. Steps 1–6 take a few minutes altogether; step 7, the cluster actually coming up, is the long one, typically **10–20 minutes**. Each phase is announced as a stable `[N/8] name: ...` progress line (the shape scripts grep, see [Automation & CI](#automation--ci)).
Wherever a step can fail, the failure is specific: every hook failure **names the Job**, prints its **last 30 log lines**, and closes with a `FIX:` line (the repair) and a `RERUN:` line (your personalized command to resume). Nothing needs diagnosing from scratch.
Each xpander image has its own version. The installer loads one release manifest that lists the matching version and SHA-256 digest for all 28 xpander images (19 xpander services, 3 agent images, 6 artifact images). It writes those pins into the values passed to Helm.
The default is the latest release. To repeat a release or install offline, pass `--release-manifest ./release-manifest.json`. A missing or invalid manifest stops the operation. [How release selection works](#releases).
Every requirement is checked and printed with the reason it matters: the registry answers `/v2/` (a 401 counts as up), representative images (`agent-controller`, `deployment-manager`) exist in the mirror, **each probed at its own pinned tag**, a usable RWO StorageClass exists, the image pins are in place (`N images pinned, each at its own version`), the org seed has its inputs (`--org-name` + `--admin-email`), and a chart source exists. Any failed item stops the run here, with nothing to clean up.
The license files are checked (JSON shape, two `xpander-license/v2` envelopes, one `kind: install` and one `kind: activation`, bound to the org id from `--org`; a legacy v1 file is checked for its envelope, expiry and the org id it carries), then applied idempotently as the `xpander-license` Secret. The chart wires it to every license-consuming service and verifies the **Ed25519 signature** against xpander's issuer public key: in the preflight hook, and again at deployment-manager boot.
The `xpander-airgap` chart is pulled from the gated OCI registry with your read token, or from your own mirror if you mirrored the chart next to the images, or from a hand-carried `.tgz` via `--chart-path`.
Your configuration is written to a temporary values file (mode 600, removed on exit) together with the pinned image manifest. Secrets never appear on the helm command line, in shell history, or in process listings.
`helm upgrade --install` runs in the background (its log path is printed). The **first** install deliberately runs without `--atomic`: `--atomic` implies `--wait`, which would hold the post-install seed hooks until every pod is Ready, while the api and agent-controller pods are themselves waiting on that seed. The smoke hook (step 7) is the real readiness gate. **Upgrades always run with `--atomic`**: a failed upgrade rolls back automatically and the previous revision keeps serving.
The chart installs through an ordered hook pipeline; the installer watches it live and reports each stage as it starts and completes:
```
preflight → keygen → data-checks → workloads → migrations → org-seed → catalog-seed → smoke
```
| Stage | What it does, and where things fail |
| - | - |
| **preflight** | In-cluster checks: StorageClass, node architecture, and the license's shape, expiry, and **Ed25519 signature**. A bad license fails here in one readable message instead of crash-looping every consumer |
| **keygen** | Every xpander's key is **minted in your cluster**: 15+ inter-service API keys, the Supabase JWTs, and the bootstrap admin password, all into the `xpander-generated-keys` Secret. **Lookup-preserve**: a key already in the Secret is never regenerated, on any upgrade. Your keys outlive the release |
| **data-checks** | External data tier only: `pg_isready` and `redis-cli ping` run **from inside the cluster**, exactly where xpander will connect from, so security-group and network-policy problems surface here, by name, before any workload starts |
| **workloads** | The data tier, Supabase stack, control plane services, and UI roll out |
| **migrations** | The **full database schema is replayed** into your in-cluster Supabase: a versioned Job per revision, kept as an audit trail. Forward-only: a schema rollback means restore-from-backup |
| **org-seed** | **Your organization is created in your own cluster**: the org the license is bound to, the bootstrap admin user, and xpander's vault. Idempotent: it re-runs safely on every upgrade |
| **catalog-seed** | The skills catalog loads from the mirrored artifacts image |
| **smoke** | The end-to-end gate: every enabled component is probed through its Service, and the install only reports success when they all answer |
A closing box prints the release facts, the **derived URLs** (with a [base domain](#domains-ingress--dns) set and no host overrides: the UI at `https://chat.`, the API at `https://api.`, Supabase at `https://supabase.`), and the **bootstrap admin password itself**, plus the command to read it again later:
```bash theme={"dark"}
kubectl -n xpander get secret xpander-generated-keys \
-o jsonpath='{.data.XPANDER_ADMIN_PASSWORD}' | base64 -d
```
The full session log (secret-scrubbed, mode 600) is saved under `~/.xpander/logs/`: `latest.log` always points at the most recent run, ready to review and share with support if you need help.
***
## Releases
Helm remains the deployment mechanism. The release manifest supplies the xpander image versions and digests to Helm; it does not install workloads itself.
The installer and mirror script default to the release manifest in the [latest release](https://github.com/xpander-ai/releases/releases/tag/latest). Each manifest identifies one complete set of 28 xpander images: 19 xpander services (among them `billing` and `openapi-spec-generator`), 3 agent runtime images, and 6 artifacts (the UI, migrations, edge functions, skills, catalog specs, and icons). A newer tag in a registry does not change this set.
* **Use the latest release:** omit `--release-manifest` when running the installer or mirror script on a connected machine.
* **Repeat one release:** retain its JSON manifest and pass the same `--release-manifest FILE` to both scripts. This also prevents a new release between mirroring and installation from changing the selected images.
* **Stop on an invalid release:** a missing, incomplete, or invalid manifest stops the operation. It does not fall back to `latest`, guess individual tags, or silently omit missing artifact images.
* **Keep the release consistent:** explicit image tag flags must match the manifest. The installer applies the release image pins over conflicting image values. Customer configuration such as registry addresses, infrastructure settings, and secrets remains separate.
The manifest covers xpander images. The chart continues to define third-party image versions. Keep the matching chart package with your release; the image manifest alone does not select a chart version.
**Keep the mirror longer than the releases you may re-install.** A release manifest pins tags. A registry lifecycle rule that keeps the last twenty images per repository spans only a few days at the current build rate. A re-install of a still-current release then fails on an image the mirror already expired. Keep hundreds of tags per repository, or exempt pinned tags from expiry. If your registry requires repositories to exist before a push, create one per image in the release. That includes `agent-harness` and `openapi-spec-generator`, plus the third-party data-tier and Supabase images and `charts/xpander-airgap`. `image_sync.sh` creates missing ECR repositories itself.
**Following a development stream instead of a release** is for a staging environment that tracks pre-release builds. Set `XPANDER_IMAGE_STREAM=dev` in the installer's environment, and pass `--stream dev` to `image_sync.sh`. Without the variable, an air-gapped install pins every image to the approved release and refuses development overrides.
Per-artifact tag flags:
| Artifact | Mirror script (`image_sync.sh`) | Installer |
| - | - | - |
| UI | `--ui-tag` | not available |
| Skills | `--skills-tag` | `--skills-tag` |
| Catalog specs | `--catalog-specs-tag` | `--catalog-tag` |
| Icon pack | `--icon-pack-tag` | not available |
| Migrations | `--migrations-tag` | `--migrations-tag` |
| Edge functions | `--edge-functions-tag` | `--edge-functions-tag` |
Other flags: `--manifest-out ` makes the mirror script write the tags it copied as a values file, to pass to the installer with `--values` last. `--release-candidate` selects a candidate release. `--registry-username xpanderaihub --registry-token ` and `--xpander-registry-token ` carry the pull credentials.
The icon pack has no installer flag: pin it with `--set ui.iconPack.image.repository=... --set ui.iconPack.image.tag=...`, or icons fall back to monograms.
Installer 0.17.1 reads the JSON release manifest with a parser that only understands the YAML mirror manifest written by `image_sync.sh --manifest-out`, so an install with `--release-manifest` alone fails. Until the fix ships, mirror with `--manifest-out mirror-pins.yaml` and pass that file to the installer with `--values mirror-pins.yaml` as the last values file, alongside `--release-manifest`; the pins then come from a file the installer can read.
**Publishing a release does not upgrade customer clusters.** Your Helm invocation, GitOps reconciliation policy, or upgrade schedule determines when it is installed. Updating a Helm repository index only refreshes the available chart list.
### Existing Helm and GitOps Pipelines
| Deployment flow | Release handling |
| - | - |
| Installer invokes Helm | Refresh the installer and mirror scripts together. They resolve the release and pass its pins to Helm. |
| Direct `helm upgrade`, Argo CD, or Flux | Supply the generated release values alongside your configuration. Helm does not fetch or validate the JSON release manifest itself. Update the chart and release image values together. |
| Fully offline installation | Transfer the complete image bundle, manifest, matching scripts and validator, and chart package before upgrading. |
Pipelines that keep old script copies or select image tags themselves need a one-time adaptation. See [CI/CD & GitOps](#cicd--gitops) for an example that downloads the manifest once and uses it throughout the upgrade.
### When the Mirror Is Empty, the Wizard Offers to Fill It
The wizard can mirror the selected release from a connected machine. Choose **Mirror them now**, provide the xpander registry pull credentials and any destination credentials, and let the copy finish before installation. ECR repositories are created automatically when the configured AWS credentials allow it.
For a sealed network, use the archive flow below. Non-interactively, `--mirror now|guide|skip` chooses the mirroring behavior; `--mirror now` needs the registry credentials. Skipping mirroring does not make missing release images available.
## Sealed / Manual Mirroring
Use `image_sync.sh` to mirror the release before installing it. Mirroring requires **skopeo and Python 3**; the Docker pull/tag/push fallback does not preserve the release digests.
On a connected workstation, download the manifest once and use that exact file for the copy and upgrade:
```bash theme={"dark"}
curl -fsSLO https://charts.xpander.ai/image_sync.sh
curl -fsSLO https://charts.xpander.ai/install.sh
curl -fsSL https://github.com/xpander-ai/releases/releases/download/latest/release-manifest.json \
-o release-manifest.json
bash image_sync.sh --source docker.io/xpanderaihub \
--dest /xpander \
--release-manifest ./release-manifest.json
```
Supply your registry credentials using the script's source/destination credential flags or configured registry authentication. `--dry-run` prints the copy plan. Keep the release JSON manifest; a single `--tag` or a legacy service-only manifest does not describe the complete release.
**Fully sealed network?** Archive on the connected side, transfer the entire directory, and import it inside:
```bash theme={"dark"}
# On a connected workstation:
bash image_sync.sh --source docker.io/xpanderaihub \
--release-manifest ./release-manifest.json --archive-dir ./xpander-images
# After transferring the complete directory, on the inside:
bash image_sync.sh --from-archive ./xpander-images --dest /xpander
```
Carry `install.sh`, `image_sync.sh`, and their matching `release_manifest.py` alongside the bundle. Obtain the validator from the immutable `release_manifest-.py` URL embedded in those scripts and save it as `release_manifest.py` beside them. The scripts verify its checksum before executing it. Connected runs download the matching validator automatically.
The archive includes a release manifest and an image index. Import validates the complete xpander image set and digests before copying. An incomplete archive must be completed on the connected side. Legacy archives require the previous importer and do not establish a release.
The chart itself is an OCI artifact. Either mirror it next to the images (`--chart-version --chart-source registry-1.docker.io/xpanderaihub/xpander-airgap`, it lands at `oci:///xpander/charts/xpander-airgap`), or pull and hand-carry the `.tgz`:
```bash theme={"dark"}
helm registry login registry-1.docker.io --username --password-stdin
helm pull oci://registry-1.docker.io/xpanderaihub/xpander-airgap --version
# copy xpander-airgap-.tgz onto the sealed-network host, then --chart-path it
```
A registry manager fits either of two patterns:
**Hosted repository: mirror into it.** The registry manager is the `--registry` target. Create a hosted Docker repository and fill it with the wizard's mirror-now step, or with `image_sync.sh` directly; `--dest-user` / `--dest-token` cover repositories behind Basic auth:
```bash theme={"dark"}
bash image_sync.sh --source docker.io/xpanderaihub \
--dest nexus.corp.example:5000/xpander \
--dest-user --dest-token
```
Then install with `--registry nexus.corp.example:5000/xpander`.
**Pull-through proxy, no mirror step.** Create a Docker *proxy* repository with Docker Hub (`https://registry-1.docker.io`) as the upstream, and set the xpander-issued read token as the proxy's **upstream** credentials. Install with the org path kept inside the registry value:
```bash theme={"dark"}
--registry //xpanderaihub
```
Images cache lazily in the proxy on their first pull: nothing to mirror. The `xpanderaihub` path segment must remain: the chart composes every image reference as `/`, so the cluster asks the proxy for `/xpanderaihub/agent-controller`, which maps to `xpanderaihub/agent-controller` upstream. The installer's tag resolution works against the proxy the same way (Docker Registry v2 API, Basic or bearer auth).
A **fully sealed** network can't use a proxy: it needs upstream reachability. Keep the two-hop archive flow above, landing in a hosted repository.
The installer prints this entire runbook, personalized with your registry and namespace, with `bash install.sh --edition airgap --guide`, and prints it automatically when it detects no reachable cluster. `--manual` goes further: the [whole install as copy-pasteable commands](/self-hosted/hybrid#advanced-review-first--manual-install), executing nothing.
***
## Data Tier: In-Cluster or External
The data tier is the one choice that is expensive to change later: the chart-managed StatefulSets own their PVCs, and moving to a managed service afterwards is a migration. The wizard asks per store; the default is both in-cluster.
Chart-managed StatefulSets on your StorageClass:
* **PostgreSQL 16**: durable history/memory tier and per-agent database provisioning
* **Redis Stack** (`redis-stack-server`): queues, cache, and knowledge-base vectors. Deliberately not plain Redis: knowledge bases are RediSearch (`FT.*`) indexes
* **MongoDB**: catalog and monitoring stores
* The Supabase stack ships its **own** pinned PostgreSQL 15 (it requires extensions managed services don't offer)
No flags needed. Set `--storage-class ` if you don't want the cluster default.
Bring your own PostgreSQL and/or a Valkey / MemoryDB cache with the search module. Interactively, the installer flags carry everything:
```bash theme={"dark"}
bash install.sh --edition airgap ... \
--pg-mode external --pg-dsn 'postgresql://xpander:password@db.internal:5432/xpander' \
--redis-mode external --redis-endpoint \
--redis-tls --redis-cluster --redis-username --redis-password
```
For a pipeline, the same choice lives in your values file, with the passwords passed as `--set` so they never land in Git:
```yaml theme={"dark"}
postgres:
mode: external
external:
host: postgres.internal.acme.example
port: 5432
redis:
mode: external
global:
redis:
endpoint:
clusterMode: true
auth:
username:
```
```bash theme={"dark"}
bash install.sh --edition airgap ... --values values.yaml \
--set keygen.overrides.POSTGRES_PASSWORD= \
--set global.redis.auth.password=
```
* **PostgreSQL**: create the role and database before the install; the role needs **`CREATEDB`** because xpander provisions per-agent databases on this server:
```sql theme={"dark"}
CREATE ROLE xpander LOGIN PASSWORD '' CREATEDB;
CREATE DATABASE xpander OWNER xpander;
```
`keygen.overrides.POSTGRES_PASSWORD` wins over every generated or derived value, which is how xpander learns the password you set.
* **Valkey / MemoryDB with the search module**: the endpoint must ship the **RediSearch (`FT.*`) commands**, or knowledge bases accept writes and return nothing.
* On MemoryDB, that means **Valkey 7.3 on the parameter group `default.memorydb-valkey7.search`**. This is a creation-time choice: it cannot be retrofitted onto an existing cluster, and it is what makes the chart's `FT.*` compatibility check pass.
* Give xpander an ACL user with `on ~* &* +@all`.
* Turn on TLS (`--redis-tls`; MemoryDB and ElastiCache with in-transit encryption answer TLS only) and cluster mode (`--redis-cluster`).
* Run **one cluster per environment**: ACLs cannot split `FT.*` index namespaces between installs. Recreating the cache means re-ingesting your knowledge-base vectors.
* Pass `--redis-username` / `--redis-password` for ACL auth, and `--redis-port` if the endpoint is not on 6379.
* The chart renders an in-cluster `redis` ExternalName Service pointing at your endpoint, so service DNS stays uniform either way.
* The connectivity probe echoes the endpoint's own auth replies (`NOAUTH`, `WRONGPASS`), so a credential mistake reads as itself.
* **MongoDB has no external mode**: it always runs in-cluster as a chart-managed StatefulSet.
* Supabase's own Postgres is **never external**: its migrations hard-require extensions RDS does not ship; it always runs in-cluster.
* **On RDS, the shortest path** is to name the master user and the initial database `xpander`; the master role already has `CREATEDB`, so no SQL runs before the install.
* **Blob storage on S3**: Supabase Storage keeps uploads, attachments and live-surface assets on an in-cluster volume by default, or in an S3 bucket you own, authenticated through the pod's identity (IRSA or EKS Pod Identity) with `credentialsSecret` left empty; see [File storage](/run/integrations/file-storage#object-storage) for the values.
**Live connectivity probes**: before installing, the installer launches a probe pod inside your namespace, the same images and commands the chart's own preflight hooks use (`pg_isready`, `redis-cli ping`), and reports reachability from where xpander will actually connect. A failed probe is a decision, not an abort: retry after fixing the network, continue anyway (the chart's pre-install hook re-checks and fails the install if the store is really unreachable), or abort with nothing changed. `--on-probe-failure retry|continue|abort` preselects that answer; non-interactive runs default to `abort` and exit with code 5.
***
## Local LLM Inference
An air-gapped install needs an LLM endpoint reachable in-network. xpander speaks the OpenAI-compatible API, so any local runtime that exposes it plugs in directly:
| Runtime | Models | Notes |
| - | - | - |
| vLLM | Llama, Mistral, Qwen | High-throughput inference; OpenAI-compatible API |
| Ollama | Llama, Mistral, Phi, Qwen | Easier to operate; good for smaller deployments |
| NVIDIA NIM | Llama, Mistral, others | Optimized GPU runtime; enterprise support |
| AWS Bedrock (private) | Anthropic, Mistral, Llama | Only for VPC deployments with PrivateLink to Bedrock: *not* fully air-gapped |
Size your inference pool separately by model; it is your own infrastructure, not part of the chart's footprint. Hosted providers (OpenAI, Anthropic, Google, Bedrock) also work when your egress policy allows them: the same [LLM provider keys](/self-hosted/hybrid#managing-llm-api-keys) apply.
Two models are declared at install level: the agents' default model, and the **gateway model** that runs entry filtering ahead of it (`global.llm.gateway.{provider,model,apiBase}` in values). LLM defaults follow **values-as-truth with snapshot convergence**. Every install and upgrade converges the organization's LLM defaults to the chart's declaration, but only when the declaration itself changed. Defaults an admin has edited in the UI survive upgrades until you deliberately change the declared value.
**Amazon Bedrock without a key.** Chat, agent task executions and the summaries around them all work on the pods' own AWS identity (EKS Pod Identity or IRSA) since xpander-sdk 2.0.503 (images built after 27 August 2026): leave `global.llm.bedrock.bearerTokenSecret` empty and set `global.llm.bedrock.region`. The role bound to the pods needs the Bedrock permissions itself (`bedrock:InvokeModel`, `bedrock:InvokeModelWithResponseStream`, `bedrock:Converse`, `bedrock:ConverseStream` on `*`, because the `global.*` inference profiles route across regions), and it must be bound to both ServiceAccounts the LLM services run as in the release namespace: `default` and `agent-controller`. The chat and task paths use those credentials directly and do not assume a second role. The account must be opted in to Bedrock's data retention mode for the models in every region a `global.` profile spans, and a sealed network needs VPC endpoints for `bedrock-runtime`, `sts` and `eks-auth`. A Bedrock API key (bearer token) in `bearerTokenSecret` is the alternative. The "IAM role" method under Settings, LLM settings, Providers is not the path for chat and tasks: it applies to the Claude Code leg only (see below). If a Bedrock entry with an IAM role exists there and chat fails, remove it, then restart the `agent-controller`, `agent-worker`, `agents`, `actions` and `functions` deployments so the old value is dropped.
A working keyless declaration, from a customer install on EKS:
```yaml theme={"dark"}
global:
llm:
defaults:
provider: amazon_bedrock
model: global.anthropic.claude-sonnet-5
gateway:
provider: amazon_bedrock
model: global.anthropic.claude-sonnet-4-6
bedrock:
region:
```
Leave `bearerTokenSecret` and `assumeRoleArn` unset. Put the Bedrock permissions on the role the pods already run as (the install's `xpander-sa-role` in that customer's case), bind it to the `default` and `agent-controller` service accounts, and upgrade the release. A separate Bedrock access role is not needed.
Claude Code on Bedrock takes its own path: it reaches Bedrock through the Agent Controller's LLM proxy, which resolves AWS auth on the controller itself. This is the only place the assume-role option applies. There too a bearer token is optional: `global.llm.bedrock.assumeRoleArn` (plus `assumeRoleExternalId`) takes the STS assume-role path, and with both the token and the role empty the controller signs with the pod's own credential chain (EKS Pod Identity or IRSA). `global.llm.bedrock.baseUrl` points that leg at your VPC endpoint on a sealed install. Fable- and Mythos-class Anthropic models additionally need the account's Bedrock data-retention opt-in, per region; the exact call is on [AI vendors](/run/integrations/ai-vendors#anthropic-on-amazon-bedrock).
The summaries xpander writes around agent work (thread titles, context compaction, evaluation judges) follow the organization's LLM settings: the org default model leads, and the install's other configured providers back it up. Nothing in that chain dials a public endpoint on a sealed install.
### A worked vLLM setup on EKS Auto Mode
One in-cluster endpoint, checked end to end on an Air-Gapped install: vLLM serving a small instruct model on a T4, registered in xpander as a custom provider. The cluster side is yours; xpander only needs the address.
**GPU capacity.** On EKS Auto Mode a `NodePool` restricted to the `g4dn` family with a `nvidia.com/gpu` taint provisions a T4 node in about two minutes. Auto Mode exposes `nvidia.com/gpu: 1` on it with no device-plugin install. The pool needs a `nodeClassRef` to the built-in class: `group: eks.amazonaws.com`, `kind: NodeClass`, `name: default`. Weights go on a PersistentVolumeClaim mounted as `HF_HOME`, so they survive a pod restart; on a sealed network they have to be on that volume already.
**Five things that stop vLLM before it serves an agent.**
1. Kubernetes writes every Service in the namespace into a pod's environment as `_PORT` (service links). A Service named `vllm` therefore injects `VLLM_PORT=tcp://...`, and vLLM refuses to start with `VLLM_PORT ... appears to be a URI`. Set `enableServiceLinks: false` on the pod, or name the Service something else.
2. A T4 GPU needs `--dtype=half`. vLLM 0.11 crash-loops on a T4 because its newer engine needs a newer GPU; `vllm/vllm-openai:v0.9.2` runs there.
3. Pass the key as the `VLLM_API_KEY` environment variable, not the `--api-key` flag. The flag prints the key in the startup log.
4. Start with `--enable-auto-tool-choice --tool-call-parser=hermes`, the two vLLM flags that let a Qwen model return function calls. xpander's **Add provider** dialog probes whether the model accepts function calls; without these flags the discovered model is marked as unable to run agents.
5. Give the model a context window well above the composed prompt. With `--max-model-len=8192` the first turn failed with vLLM's `400 This model's maximum context length is 8192 tokens. However, you requested 8298 tokens`. The conversation shows **Unknown model error**. The controller logs `Non-retryable model provider error: Unknown model error` next to a `[prompt-budget] system_message_tok=...` line, which sizes the prompt it composed. `--max-model-len=32768` ran. For a custom model the controller's context optimizer also warns `unknown model.id ... defaulting to 128,000 window`.
The manifests, with the lab's account-specific values replaced by placeholders:
```yaml theme={"dark"}
apiVersion: karpenter.sh/v1
kind: NodePool
metadata:
name: gpu
spec:
template:
metadata:
labels:
workload: gpu
spec:
nodeClassRef:
group: eks.amazonaws.com
kind: NodeClass
name: default
requirements:
- key: eks.amazonaws.com/instance-family
operator: In
values: ["g4dn"]
- key: eks.amazonaws.com/instance-size
operator: In
values: ["xlarge", "2xlarge"]
- key: karpenter.sh/capacity-type
operator: In
values: ["on-demand"]
- key: kubernetes.io/arch
operator: In
values: ["amd64"]
taints:
- key: nvidia.com/gpu
value: "present"
effect: NoSchedule
terminationGracePeriod: 10m
limits:
cpu: "16"
nvidia.com/gpu: "2"
disruption:
consolidationPolicy: WhenEmpty
consolidateAfter: 10m
---
apiVersion: v1
kind: PersistentVolumeClaim
metadata:
name: vllm-models
namespace:
spec:
accessModes: ["ReadWriteOnce"]
storageClassName:
resources:
requests:
storage: 40Gi
---
apiVersion: apps/v1
kind: Deployment
metadata:
name: vllm
namespace:
labels: { app: vllm }
spec:
replicas: 1
strategy: { type: Recreate }
selector: { matchLabels: { app: vllm } }
template:
metadata:
labels: { app: vllm }
spec:
enableServiceLinks: false # a Service named vllm would inject VLLM_PORT=tcp://... and stop vLLM
nodeSelector:
workload: gpu
tolerations:
- key: nvidia.com/gpu
operator: Exists
effect: NoSchedule
containers:
- name: vllm
image: docker.io/vllm/vllm-openai:v0.9.2 # from your mirror; 0.11 does not run on a T4
args:
- --model=Qwen/Qwen2.5-1.5B-Instruct
- --served-model-name=qwen2.5-1.5b-instruct
- --dtype=half
- --max-model-len=32768 # 8192 fails the first turn: the composed prompt is larger
- --gpu-memory-utilization=0.90
- --host=0.0.0.0
- --port=8000
- --enable-auto-tool-choice # xpander's Add provider dialog probes for this
- --tool-call-parser=hermes
env:
- name: HF_HOME
value: /models
- name: VLLM_API_KEY # the variable, not --api-key: the flag logs the key
valueFrom:
secretKeyRef: { name: vllm-api-key, key: key }
ports:
- containerPort: 8000
resources:
limits:
nvidia.com/gpu: 1
memory: 12Gi
requests:
cpu: "2"
memory: 8Gi
volumeMounts:
- { name: models, mountPath: /models }
- { name: shm, mountPath: /dev/shm }
readinessProbe:
httpGet: { path: /health, port: 8000 }
initialDelaySeconds: 60
periodSeconds: 15
failureThreshold: 60
volumes:
- name: models
persistentVolumeClaim: { claimName: vllm-models }
- name: shm
emptyDir: { medium: Memory, sizeLimit: 2Gi }
---
apiVersion: v1
kind: Service
metadata:
name: vllm
namespace:
spec:
selector: { app: vllm }
ports:
- port: 8000
targetPort: 8000
```
### Register the endpoint in xpander
1. Open **Settings > LLM settings** and click **Add custom provider**. The dialog is titled **Add provider**.
2. **Name** is free text. **Slug** is derived from it, lowercase with underscores, and stays stable. **Protocol** is **OpenAI-compatible**. **Base URL** is the address the pods reach, for example `http://vllm..svc.cluster.local:8000/v1`.
3. **API key**: **No key (local or unauthenticated server)**, **Use an existing key**, or **Create a new key** with a **Key name** and the **API key** (the value in `VLLM_API_KEY`).
4. Under **Models**, click **Test connection**. A reachable endpoint answers **Reachable** with the round-trip time and lists the models it serves; a model that accepts function calls carries a `tools` badge. Click **Add** on the model, and give it a **Display name** if you want one.
5. Click **Add provider**. The provider row reads **OpenAI-compatible**, how many of its models are in the catalog, and **Reachable**.
6. Open the provider's model list and choose **Set model cost** from the model row's menu. The dialog says what it is for: "Agents can use the model once it has a cost." Enter the **Price per 1M tokens (USD)**: **Input** and **Output**, and optionally **Cache read** and **Cache write**. These prices measure credit burn for the model; they are never charged. **Who can use it** is **Everyone in the workspace** or **Specific groups and people**. Click **Save cost**.
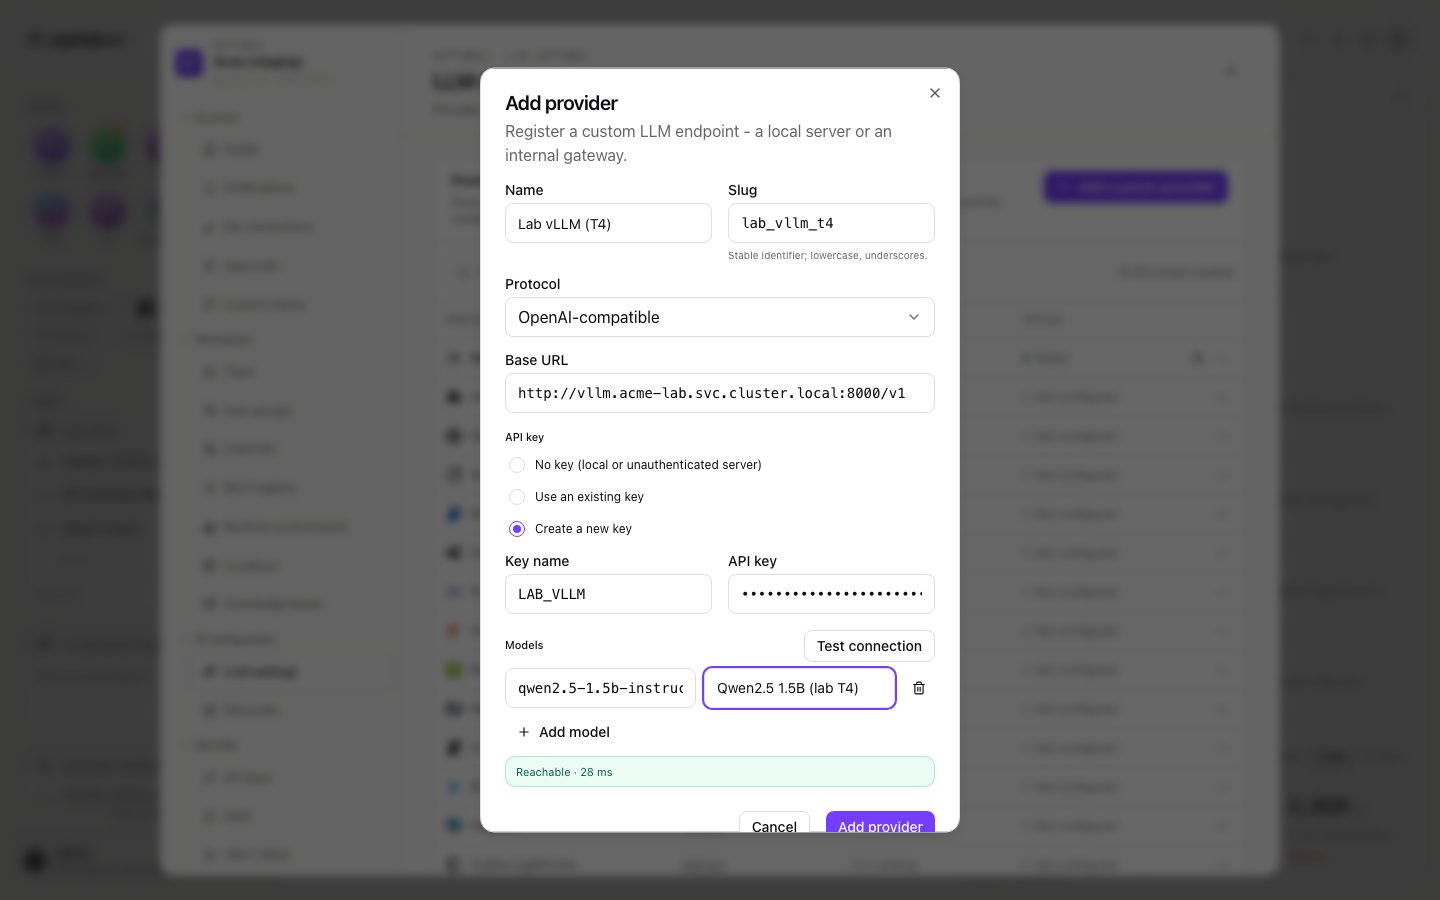
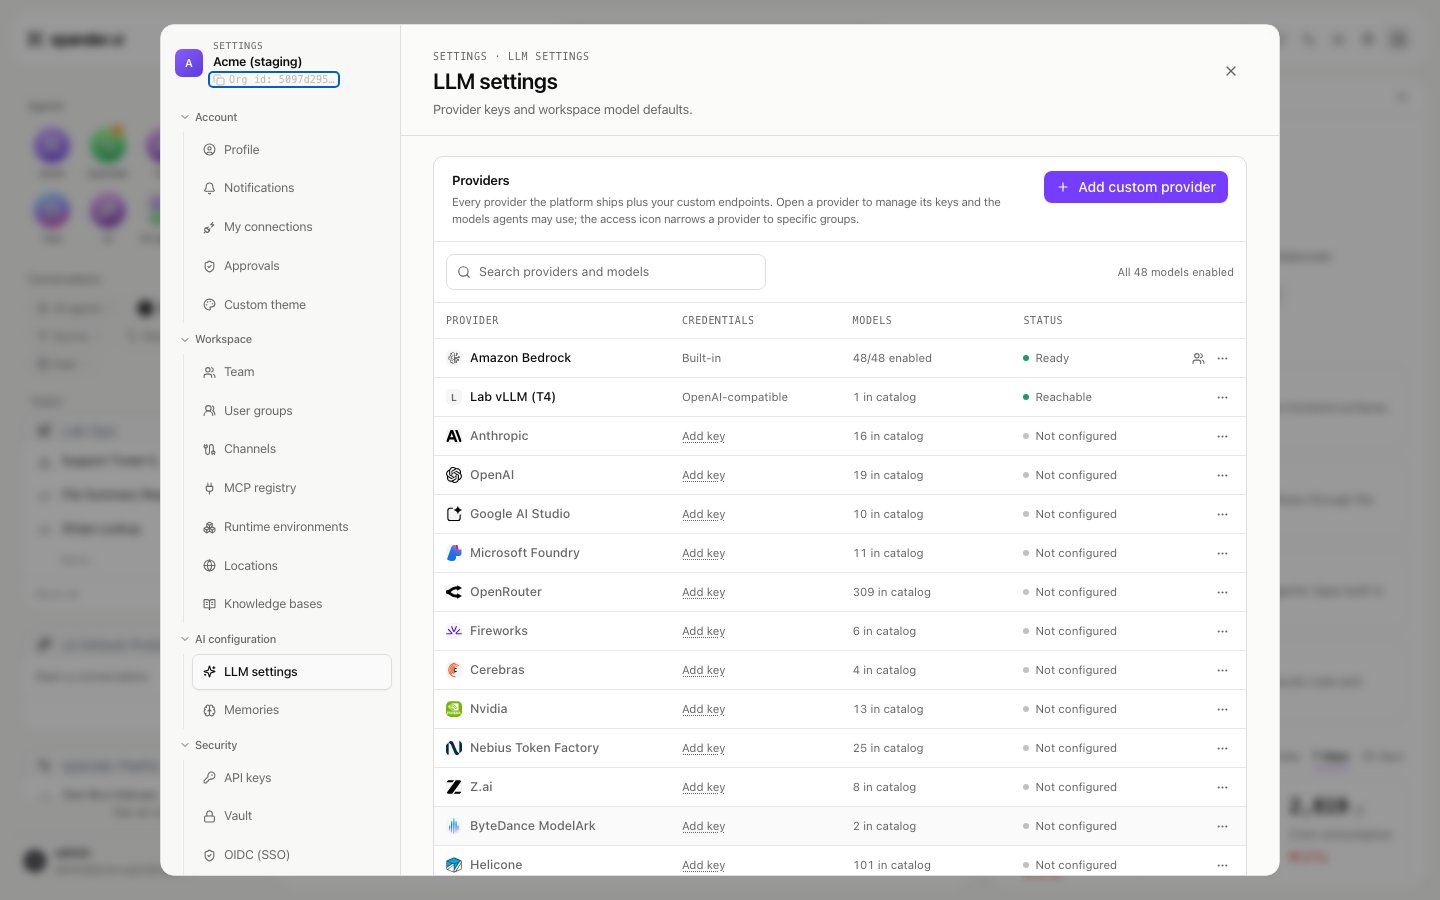
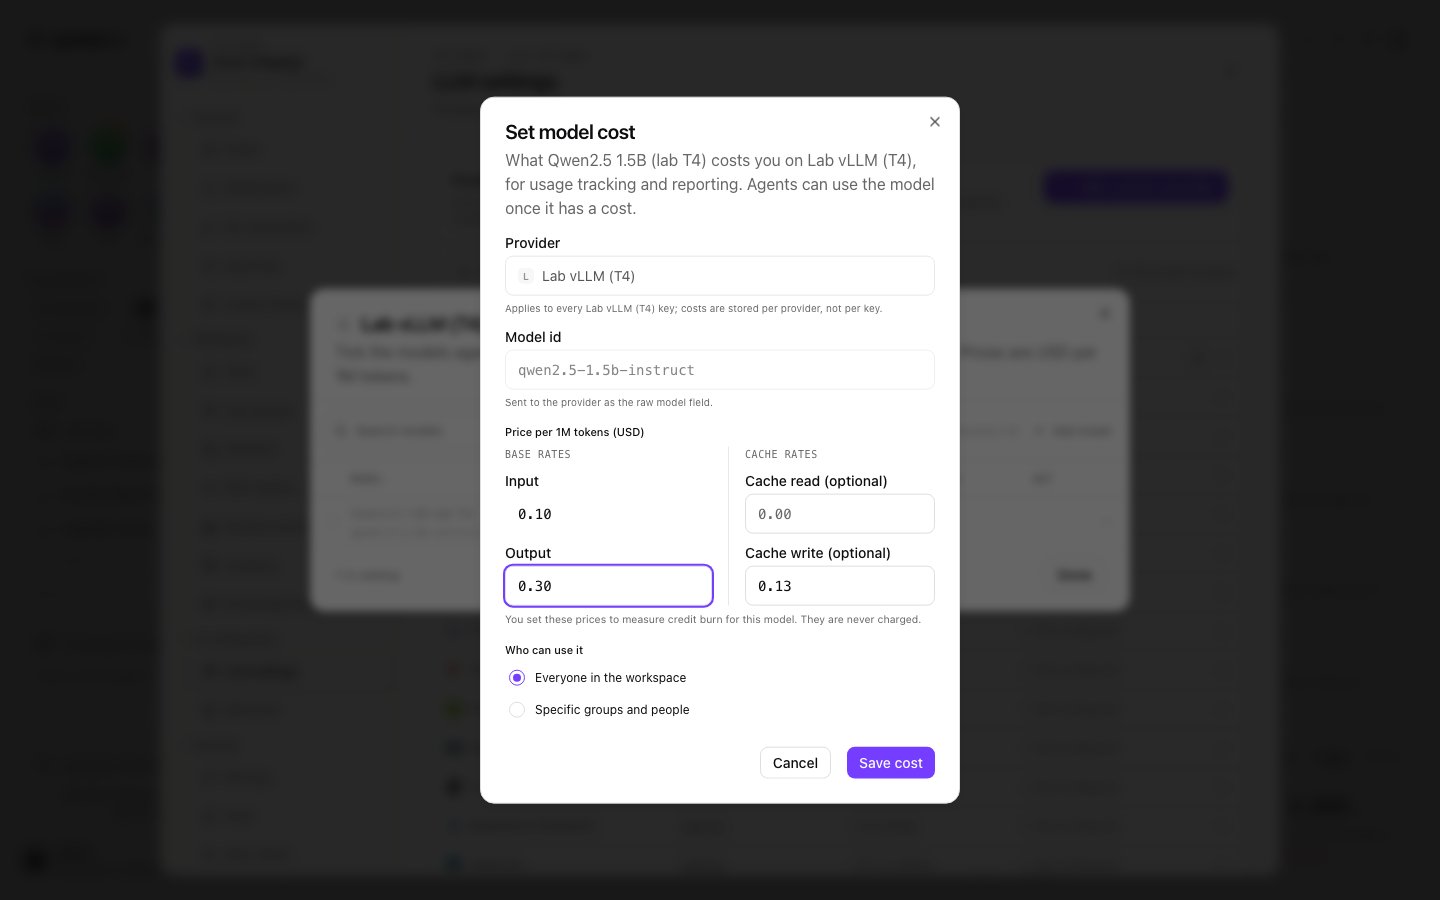 `POST /v1/agents` accepts only the built-in providers in `model_provider`; a custom slug is refused with `422`. Agents reach a custom provider through OpenCode. In the composer's **Harness and model** popover, the **OpenCode** pane lists every provider, custom ones included; the model becomes selectable once it has a cost, and the provider's row then counts it as enabled. The conversation header names what runs, for example **OpenCode · Qwen2.5 1.5B (lab T4)**, and the controller's `gateway turn start` line carries `model=:/`. vLLM logs the call as `POST /v1/chat/completions 200`.
***
## The executor fleet on Air-Gap
Every agent runs on Claude Code, Codex or OpenCode. Their turns run on the executor fleet the chart always renders; sizing and node prerequisites are on [Sizing and requirements](/self-hosted/sizing). What an Air-Gapped operator configures beyond that:
| Concern | What to set |
| - | - |
| **An LLM route** | The CLIs never call a provider directly; every model call goes through the controller's LLM proxy. Preflight refuses the install unless a route exists: an org default provider (`global.llm.defaults` or `global.llm.bedrock`), a gateway provider (`global.llm.gateway`), a per-provider in-cluster endpoint (`LLM_PROXY__BASE_URL`, for example `LLM_PROXY_ANTHROPIC_BASE_URL`), or `global.fleet.llmProxyUrl`. On a sealed install (`global.network.internetEgress: false`) a leg with no override is refused rather than dialled |
| **Which CLI, provider and model a new agent gets** | Explicit choices in the create always win. A defaulted create follows the **organization's default LLM** (Anthropic maps to Claude Code, Bedrock with an Anthropic model to Claude Code on Bedrock, OpenAI to Codex, any other routed provider to OpenCode), then the chart knobs `global.harness.defaultModels.{claudeCode,codex,opencode,xpander}` and `global.harness.defaultProviders.claudeCode` (chart 0.12.10 and later), then the baked defaults. With no org default LLM and no knobs, a new Claude Code agent runs **Fable 5.1 over Anthropic direct**, so the install needs an Anthropic key on the controller, or Bedrock (with the data-retention opt-in) declared instead. Set the org default in Settings > LLM once and the knobs become the fallback |
| **Bedrock auth** | `global.llm.bedrock.region`, then one of: `bearerTokenSecret`, `assumeRoleArn` (+ `assumeRoleExternalId`), or nothing for EKS Pod Identity / IRSA; `baseUrl` for the VPC endpoint. Fable- and Mythos-class models need the per-region data-retention opt-in on the signing account, including an organization's own Bedrock key account |
| **The license** | The activation license must carry the fleet entitlement (`harness / containers`); otherwise creating an agent is refused on the install. Re-issue the activation file if it does not |
| **CLI versions with no registry** | Seal the CLIs on a connected machine (`python -m xpander_harness.cli_updates --root /tmp/cli bundle --out cli-bundle.tar.gz`), put the tarball on a PVC and set `global.fleet.cliBundle.enabled: true` with `global.fleet.cliBundle.pvc`; a post-install Job imports it into every executor volume |
| **Capacity** | `global.fleet.replicas` fixed for peak (the sealed-network posture), or KEDA with `global.fleet.keda.enabled` after mirroring it with `image_sync.sh --with-keda` |
| **Claude Code on Bedrock** | `global.harness.defaultProviders.claudeCode: amazon_bedrock` and `global.harness.defaultModels.claudeCode: `. Without them a defaulted agent targets Anthropic directly and its first turn fails with `503 no anthropic credential configured for harness agents` |
| **Fleet volumes on a cluster that provisions storage on demand** | `global.fleet.storage.createClass: true` with `global.fleet.storage.provisioner` set to the cluster's CSI driver (`ebs.csi.eks.amazonaws.com` on EKS Auto Mode), so the XFS class with project quotas is created on the right provisioner |
***
## AI Skill Generation
Air-gapped installs include the skill-generation pipeline: upload an OpenAPI spec in the UI (`Connectors` → `Create connector`) and the `openapi-spec-generator` service enriches it into a full skill (operation grouping, naming, descriptions, summaries, and validation) through a multi-step LLM pipeline. Runs execute in the background; generated skills can be deleted, and a new spec version can be uploaded over an existing skill. The air-gap license carries the entitlement for this (`Custom connectors` in the license panel), and the generator's image is part of the standard mirrored set.
The generator runs on **exactly one LLM provider**, decided at install time: Bedrock when the install has Bedrock configured, otherwise OpenAI when an OpenAI key was provided. That one provider powers every pipeline step and the embeddings, and the service refuses runs when its provider's credentials are absent rather than degrading quietly. **With neither provider, the generator is not installed at all** and skill creation in the UI is **spec-only**: the spec is ingested as-is, with no AI enrichment (the UI flag `VITE_CONNECTOR_AI_ENRICHMENT` is set for you).
The generator writes the specs it works on to an object store bucket, on **both** the `catalog` and the `openapi-spec-generator` services; without it the upload step fails on a missing bucket name. The bucket must have **versioning enabled**: the generator lists object versions to find the latest spec and fails on an unversioned bucket.
```yaml theme={"dark"}
catalog:
env:
OAS_GEN_BUCKET_NAME:
AWS_DEFAULT_REGION:
openapi-spec-generator:
env:
OAS_GEN_BUCKET_NAME:
AWS_DEFAULT_REGION:
```
On Bedrock, the generator follows `global.llm.bedrock.region` and falls back to **us-west-2** when it is unset. Its default model IDs are US cross-region inference profiles, so the region it lands on must be a US one, and the IAM policy / PrivateLink endpoint must cover Bedrock there.
***
## Custom Actions and Code Execution
Custom actions and code run in short-lived sandbox jobs started by the `actions` service. On a multi-tenant cloud those jobs resolve public DNS only; on a single-tenant installation the point of a custom action is often to reach an internal system, so hand the jobs the cluster's resolver:
```yaml theme={"dark"}
actions:
env:
XPANDER_SANDBOX_DNS: # 172.20.0.10 on EKS; kubectl -n kube-system get svc kube-dns
```
The job image is xpander's sandbox image from your mirror; `api.env.SANDBOX_IMAGE` overrides it when you track a development stream.
***
## The License
New air-gap installs are licensed with **two sealed files** (`install.json` + `activation.json`, the `xpander-license/v2` format), which enables renewal without a reinstall and enforces seat/agent caps. See **[Two-File Licensing](/self-hosted/licensing)**. The single-file flow below (`xpander-license/v1`) still works for installs issued that way.
The installer validates both sealed envelopes locally (format, one `kind: install` and one `kind: activation`, the org id from `--org`) and creates the `xpander-license` Secret with both files as keys, idempotently:
```bash theme={"dark"}
kubectl -n xpander create secret generic xpander-license \
--from-file=install.json=./install.json \
--from-file=activation.json=./activation.json \
--dry-run=client -o yaml | kubectl -n xpander apply -f -
```
The chart's preflight hook then verifies the **Ed25519 signature** against `global.license.publicKey`, and deployment-manager re-verifies at boot: it refuses to start on a bad signature.
* **Your own `--values` file**: the installer generates the `global.license` block (`secretName`, `installKey`, `activationKey`, `publicKey`) into its own values. When you also pass `--values` of your own, pass `--set global.license.installKey=install.json --set global.license.activationKey=activation.json --set global.license.publicKey=` as well, or your file displaces the installer's license block.
* **Renewing**: renewal re-issues only `activation.json`. Replace that one key in the Secret (leave `install.json` as it is) and redeploy: roll the license consumers, run `install.sh upgrade` by hand, or let your pipeline re-run its install. License consumers carry a checksum annotation over the Secret, so a redeploy rolls them onto the new file. No reinstall, no re-mirror. Steps: [Renewing: re-activate](/self-hosted/licensing#renewing-re-activate).
* **Expired activation**: the installer warns at the license phase and the chart's preflight refuses a fresh install. A running install degrades in stages instead of stopping: `GET /v1/license/status` on the API (with a signed-in user's bearer token) returns the current state, `valid`, `expiring`, `grace` or `expired`, plus the deployment and granted features; alert on anything past `expiring`.
* **Single-tenant**: the license binds one organization; the org seed creates exactly that org.
* **Legacy single file** (`xpander-license/v1`): `--license-file ./license.json` creates the Secret with one `license.json` key, wired through `global.license.key`. Renewal on that path is a new `license.json` in the Secret plus the same redeploy.
***
## Domains, Ingress & DNS
One `--domain` names every public host. Give the installer a base domain, `xpander.acme.internal`, and the chart derives the whole browser-facing set from it:
| Host | Serves |
| - | - |
| `chat.` | The web UI: the address your users open |
| `api.` | The REST API |
| `agent-controller.` | SDK calls and the UI's chat backend |
| `supabase.` | Auth, storage, and edge functions (the `supabase-kong` gateway) |
| `webhook.` | Webhook triggers |
| `client-auth.` | OAuth flows for skills, SSO login |
| `actions.` | The actions service |
These names are the chart's defaults. A reference customer install renames most of them:
* `app.` for the UI
* `auth.` for Supabase
* `api.`
* `chat.` for agent-controller
* `hooks.` for the webhook service
* `links.` for short links (the `functions` Service)
* `actions.` and `client-auth.`
* `dm.internal.` for deployment-manager, on a second, internal ingress class (`deployment-manager.ingress.className`), because remote runtimes and the edge functions reach it over a backchannel rather than the user-facing path
Each host is set with `.ingress.host` (the UI also with `--ui-host`). The stack mints and validates URLs against these origins, so move the matching knobs in the same change:
| Host you rename | Knobs that must follow it |
| - | - |
| UI (`chat.` / `app.`) | `ui.ingress.host` or `--ui-host`; `supabase.auth.siteUrl`; `supabase.edgeRuntime.functionsEnv.APP_URL`; `client-auth.env.APP_URL`; `ui.env.VITE_PLATFORM_URL` |
| Supabase gateway (`supabase.` / `auth.`) | `supabase.ingress.host`; `supabase.auth.apiExternalUrl`; `supabase.storage.publicUrl`; `supabase.edgeRuntime.publicUrl`; `global.assetStore.publicUrl`; `ui.env.VITE_SUPABASE_URL` |
| API (`api.`) | `api.ingress.host`; `api.env.API_URL`; `ui.env.VITE_AGENTS_API_URL` |
| agent-controller (`agent-controller.` / `chat.`) | `agent-controller.ingress.host`; `ui.env.VITE_CHAT_BACKEND_URL` (`https:///chat-backend/{agent_id}`) |
| Webhook (`webhook.` / `hooks.`) | `webhook.ingress.host`; `supabase.edgeRuntime.functionsEnv.INBOUND_GW_URL`; `ui.env.VITE_WEBHOOK_URL` |
| Short links (`links.`, required when agents share links) | `functions.ingress.host`; `global.shortLinks.publicUrl` (its `/s/*` path must land on the `functions` Service) |
| actions, client-auth | `actions.ingress.host`, `ui.env.VITE_ACTIONS_SERVICE_URL`; `client-auth.ingress.host`, `ui.env.VITE_CLIENT_AUTH_URL` |
| deployment-manager (`dm.internal.`, required when a remote location connects) | `deployment-manager.ingress.host` and `className` (an internal class); `supabase.edgeRuntime.functionsEnv.DEPLOYMENT_MANAGER_PUBLIC_URL` |
| Every install that sets hosts by hand | `supabase.edgeRuntime.functionsEnv.AGENT_CONTAINER_INGRESS_DOMAIN` (agent workspaces), `ui.env.VITE_LICENSE_MODE: "true"`, `ui.env.VITE_EMAIL_DOMAIN` when agents have mailboxes, and `ui.extraEnv` with `VITE_SUPABASE_ANON_KEY` read from the `xpander-generated-keys` Secret |
Setting the domain **is** the publish decision. An Ingress renders for each of these services. An explicit `.ingress.enabled: false` keeps one private; `global.ingress.enabled: false` suppresses all of them, for clusters that manage their own ingress objects. The base domain also derives the **UI's runtime configuration**: Xpander Chat needs to know its Supabase, API, and chat-backend origins at boot. Without a domain, or explicit `ui.env` overrides, a browser on a sealed network would be pointed at origins it cannot reach.
Overrides and knobs:
* `--ui-host ` replaces the derived `chat.` only; any other host is overridable per service via `.ingress.host` in values (the table above lists the URL knobs each rename drags along).
* `--ingress-scheme https|http` (default `https`) sets how the browser reaches those hosts: it feeds every derived URL. Use `http` only for rigs without certificates.
* No ingress controller is assumed. Set the class and annotations per component (`.ingress.className` / `annotations`) or once for all of them via `global.ingress.className` / `global.ingress.annotations`.
**TLS** is the standard Kubernetes Ingress `tls:` block, passed through verbatim, per component (`.ingress.tls`) or once via `global.ingress.tls`. Terminate at your controller with certificates that cover every host you publish (a wildcard `*.xpander.acme.internal` covers the derived set; an internal host such as `dm.internal.` sits one level deeper and needs its own wildcard):
```yaml theme={"dark"}
global:
ingress:
className: traefik
tls:
- hosts: ["*.xpander.acme.internal"]
secretName: xpander-wildcard-tls
```
**TLS at a cloud load balancer** is the other pattern. An AWS ALB, an Azure Application Gateway or a Google load balancer terminates TLS with a managed certificate that covers every host. A wildcard covers only one level: `*.xpander.acme.example` does not cover `*.staging.xpander.acme.example`. The Ingress objects carry the controller's annotations and no `tls:` block at all. On EKS Auto Mode, put the group name in an `IngressClassParams` object rather than in the `alb.ingress.kubernetes.io/group.name` annotation, which Auto Mode ignores. Otherwise every Ingress gets its own load balancer. The load balancer exists only after the first Ingress is created, so DNS records that alias it are a second pass after the install.
### Making the Hosts Resolve
Create records in the DNS zone your users' machines resolve. A wildcard is simplest:
```
*.xpander.acme.internal. CNAME
```
Or one explicit record per published host (the table above) when a wildcard is not allowed.
Expose the ingress controller on an **internal** load balancer reachable over the VPN, then point the records at it. In a sealed VPC the private subnets need the `kubernetes.io/role/internal-elb=1` tag and the Service the `aws-load-balancer-internal` annotation: see [Troubleshooting](#troubleshooting) for the exact commands.
No DNS yet? One port-forward to the ingress controller serves every published host, because the controller routes by `Host` header. **Forward to the real scheme port**: 443 for https, 80 for http. Xpander Chat's derived origins carry no port number, so a forward on a non-standard local port serves the login page but breaks every call Xpander Chat makes afterwards. Binding 443/80 locally needs admin/root on macOS and Linux:
```bash theme={"dark"}
sudo kubectl -n port-forward svc/ 443:443
# installed with --ingress-scheme http, forward port 80 instead:
sudo kubectl -n port-forward svc/ 80:80
```
```
# /etc/hosts
127.0.0.1 chat.xpander.acme.internal api.xpander.acme.internal agent-controller.xpander.acme.internal supabase.xpander.acme.internal webhook.xpander.acme.internal client-auth.xpander.acme.internal actions.xpander.acme.internal
```
Then open `https://chat.xpander.acme.internal` (or `http://…` for an `--ingress-scheme http` install). No port in the URL.
**Sealed networks:** public DNS records for these hosts are pointless without a path in: resolution has to happen where your users are (the internal zone, or VPN-side DNS). The domain itself never needs to exist on the public internet.
***
## Signing In
The install ends with the summary box printing the derived URLs **and the bootstrap admin password**; the release NOTES (`helm get notes xpander -n xpander`) repeat the commands. With no external dependency configured, sign-in still works:
1. **Bootstrap password** (default): open the UI (`https://chat.`) at `/login-password` with your `--admin-email` and the password from the summary; read it again any time:
```bash theme={"dark"}
kubectl -n xpander get secret xpander-generated-keys \
-o jsonpath='{.data.XPANDER_ADMIN_PASSWORD}' | base64 -d
```
2. **Email OTP without SMTP**: the login page's email flow works with no mailer. The code is generated and stored, just not sent. Print it with the chart's `scripts/get_login_code.sh `. With SMTP configured (`global.smtp.*` in values), the same codes arrive by email. On installs with inbound agent mailboxes, agents' email replies deliver through the same relay. `INBOUND_EMAIL_REPLY_DOMAIN` controls the From domain, and the SMTP identity must be allowed to send as the agents' mailbox subdomain.
3. **SSO with your identity provider (OIDC)**: the SSO button is driven by the OIDC configuration an administrator enters in Xpander Chat (Settings, OIDC), served by the `client-auth` component, not by GoTrue's external providers. Setup, IdP client settings, the Keycloak `preferred_username` note and troubleshooting: [SSO with your identity provider](/self-hosted/sso). Google and GitHub social buttons remain GoTrue providers (`supabase.auth.extraEnv`).
No domain set yet? Port-forward to the UI first:
```bash theme={"dark"}
kubectl -n xpander port-forward svc/ui 8080:80 # then http://localhost:8080
```
**Access tokens live one day.** `supabase.db.jwtExpiry` defaults to `86400`: a signed-in user's access token stays valid for a day and the session renews through the rotating refresh token. One value feeds GoTrue, PostgREST and the database setting, so an override moves all three together. Tokens minted before an upgrade keep their old expiry until they refresh, and the migrations hook re-applies the database side on every upgrade, so an install born with the older one-hour default converges too.
***
## Upgrading an Air-Gapped Install
### Slack handle management compatibility
For releases that include administrator-authorized [Slack agent handles](/run/integrations/slack#authorize-handle-management), mirror the matching Supabase migrations image and bots image before upgrading the chart. The migrations image must include migrations `20260910231402` and `20260911192635`. The corresponding chart's post-migration check requires `get_slack_handle_authorization`, `save_slack_handle_authorization`, and `complete_slack_handle_authorization`; an older migrations image fails this compatibility check.
Do not upgrade the chart alone before those images are published and available in your mirror. Use the matching release artifacts together. For your installation's Slack app, include `usergroups:write` in its **User Token Scopes**, then complete administrator consent in **Settings → Channels → Slack**. The consent token is encrypted in the installation's local Supabase Vault; no new static token or environment variable is needed.
Slack requires explicitly allowed connectivity and cannot operate in a fully disconnected installation. This upgrade does not enable Slack connectivity or agent handles automatically.
### Upgrade procedure
Check the [latest release](https://github.com/xpander-ai/releases/releases/tag/latest) for updates. An air-gap upgrade is two steps, **in this order**:
The release pins image digests, so upgrading before mirroring can leave pods in `ImagePullBackOff`. Re-run the mirroring for the target release (`curl -fsSLO https://charts.xpander.ai/image_sync.sh` and run it against your registry as in [Sealed / manual mirroring](#sealed--manual-mirroring)), and hand-carry the new chart `.tgz` if your install host can't pull it over OCI.
```bash theme={"dark"}
bash install.sh upgrade --chart-path xpander-airgap-.tgz \
--release-manifest ./release-manifest.json
```
The upgrade subcommand infers the deployment from the installed chart and reuses the values the release was installed with (`helm get values`). It loads the release pins over the previous image values. Pass the same manifest used for mirroring; if the manifest cannot be loaded or validated, the upgrade stops. Upgrades run with `--atomic`, which rolls back workload changes on failure; database migrations remain forward-only. This is the hand-driven path; a pipeline should use the [declarative re-install](#declarative-re-install-for-ci) below instead.
### Declarative re-install for CI
A pipeline should inherit nothing from the release it is upgrading. Run install semantics on every deploy: `bash install.sh --edition airgap ...` with the full set of values files, the release manifest and mirror pins, the license flags and `--org`, exactly as on day one. Against an existing deployed release the installer adds `--atomic` by itself, so a failed run still rolls back. The reason to avoid `install.sh upgrade` in CI is what it inherits: the reference customer pipeline once let a stored digest ride along and ran a stale image on staging for four days before anyone noticed. Two settings go with that path:
* **`--helm-timeout 20m`** (the default is `30m`). Upgrades run `--atomic`, and the rollback waits with the same timeout, so budget twice the value plus a few minutes for hooks inside your job's credential lifetime. A one-hour OIDC session cannot host a 30-minute timeout with its rollback.
* **Heal before you run.** The installer refuses to install over a release in `pending-install`, `pending-upgrade` or `failed`. Run `helm history xpander -n xpander`, then `helm rollback xpander -n xpander`, or `helm uninstall xpander -n xpander` when no deployed revision exists (the `xpander-generated-keys` Secret survives an uninstall). Delete Failed-phase pods and failed hook Jobs first so the new run starts clean.
* **Pin the environment id on every re-install.** The first install creates the organization's default location, the runtime environment its agents run in, and a later install cannot point it at a new id. A pipeline that re-runs the install must therefore pass `--env ` after the first run. Read the id from xpander's database before installing:
```bash theme={"dark"}
kubectl -n xpander exec supabase-db-0 -c postgres -- psql -U supabase_admin -d postgres -tAc \
"SELECT id FROM public.organization_environments WHERE is_default LIMIT 1"
```
* **Wait for Helm's own verdict.** The installer's stage watcher exits on the first failed hook pod, and a pod evicted while the cluster rebalances counts even though its Job retries and succeeds. When `install.sh` exits non-zero while its `helm upgrade --install xpander` process is still running, do not kill that process: killing Helm mid-upgrade strands the release in `pending-upgrade`. Wait for Helm to finish and read the release status; a retried hook pod under a Job that completed is not a failure.
* **`global.upgradeStrategy: replace`** on clusters that provision nodes on demand. A surge upgrade of every Deployment can cascade into node-provisioning waves that outlive Helm's timeout and roll back a healthy upgrade; `replace` recreates pods in place instead.
**The fleet and `--atomic`.** `--atomic` waits for the executor fleet like any other workload. This has two consequences.
A **running harness turn holds the roll**: on `SIGTERM` an executor drains for up to `global.fleet.executor.drainSeconds` (3600 s) before the replacement pod appears. A roll during a long turn takes as long as that turn. The installer's timeout covers it. On a hand-driven `helm upgrade`, give `--timeout` at least the drain window, or upgrade in a quiet period. A turn still running at the deadline is stopped with "The executor is restarting; send the message again to continue where it left off." It resumes on the new pod when the user sends again.
An **idle executor does not stall an upgrade.** On a live cluster without the fleet's StorageClass, the chart renders the executor at zero replicas and records why on the `xpander.ai/fleet-idle-reason` annotation. The installer skips zero-replica workloads when it verifies the release.
A first install runs without `--wait`/`--atomic` on purpose: the post-install smoke hook is its readiness gate.
What survives what:
* **Generated keys survive every upgrade**: the keygen hook is lookup-preserve, the `xpander-generated-keys` Secret is Job-created (never Helm-rendered), and rollback never rewinds it.
* **`helm rollback xpander ` restores any prior revision**: everything the chart owns is release-versioned.
* **Except the database schema.** Migrations run as a versioned Job per revision (kept as the audit trail) and are forward-only: a schema rollback means restore-from-backup, never an automatic down-migration.
* **Settings that converge on every upgrade**: the one-day access-token lifetime (`supabase.db.jwtExpiry`) is re-applied on the database side by the migrations hook, so an install born before that default cannot drift back to one hour.
**Avoid `--reuse-values` on air-gap upgrades** (the installer's upgrade flow does the right thing; this applies to hand-driven `helm upgrade`). `--reuse-values` replays the previous release's *computed* values, which can resurrect settings the new chart version deliberately removed: the known case is a stale edge-runtime placeholder image pin that leaves a crash-looping Deployment failing every `--atomic` upgrade. Re-supply your values files instead, or clear the stale pin once with `--set supabase.edgeRuntime.image.repository=null --set supabase.edgeRuntime.image.tag=null`.
***
## Automation & CI
The installer is built to be driven by scripts, CI pipelines, and coding agents:
* **Every prompt has a flag.** With `--non-interactive` nothing is read from the terminal, even when one exists: missing required values exit 2 with the usage and a completed rerun line rather than blocking. It implies `--yes` and `--on-probe-failure abort`.
* **Stable progress output.** Progress is one line per transition in a grep-friendly shape, `[3/8] license: ok`, and `--quiet` reduces output to phase lines and the outcome only. Color is emitted only when stdout is a terminal.
* **`status` is the poll target.** A read-only health report: edition, chart, release status, hook jobs, workload readiness, and URLs. `--json` emits one JSON object.
**Exit codes:**
| Code | Meaning |
| - | - |
| `0` | Success |
| `1` | Install or upgrade failure (`status`: degraded) |
| `2` | Usage error, or a required flag missing with no terminal |
| `3` | `status`: no such release installed |
| `4` | Preflight failure (missing helm/kubectl, unreachable cluster, version too old) |
| `5` | External data-tier probe failed and `--on-probe-failure` was `abort` |
**Air-gap, end to end, no terminal** (use the release manifest already mirrored):
```bash theme={"dark"}
bash install.sh --non-interactive --quiet \
--edition airgap --release-manifest ./release-manifest.json \
--org --install-license-file ./install.json --activation-license-file ./activation.json \
--registry registry.example:5000/xpander \
--org-name "Example Inc" --admin-email ops@example.com \
--domain xpander.example.internal --storage-class gp3 \
--on-probe-failure abort
```
If the registry might not be mirrored yet, add `--mirror now --xpander-registry-token `. Without a `--mirror` answer, a non-interactive run against an empty mirror exits 2 with the options spelled out.
**Poll until healthy:**
```bash theme={"dark"}
until bash install.sh status --quiet; do sleep 30; done
```
### Reference values file
The keys a complete production values file carries, with the reason each exists. Hosts, bucket names and endpoints are placeholders a pipeline renders from its infrastructure outputs; passwords never appear here (pass them with `--set`), and image pins come from the mirror manifest passed last.
```yaml theme={"dark"}
global:
upgradeStrategy: replace # in-place recreation; surge upgrades cascade into node waves on autoscaled clusters
imageRegistry: / # every image is pulled from the mirror
license:
secretName: xpander-license
smtp: # one block feeds sign-in mail, invitations and xpander's notifications
host: email-smtp..amazonaws.com
port: 587
starttls: true
user:
passwordSecret: { name: xpander-smtp, key: password }
adminEmail: admin@
senderName: xpander
assetStore: { publicUrl: https://auth. }
shortLinks: { publicUrl: https://links. }
# mcp.publicUrl unset: Settings > Channels lists MCP as not configured until you set the install's MCP origin
llm:
defaults: { provider: amazon_bedrock, model: global.anthropic.claude-sonnet-5, apiBase: "", credentialsKey: "" }
bedrock: { region: us-west-2 } # may differ from the cluster's region
gateway: { provider: amazon_bedrock, model: global.anthropic.claude-sonnet-4-6 }
harness:
defaultProviders: { claudeCode: amazon_bedrock }
defaultModels: { claudeCode: global.anthropic.claude-sonnet-5 }
fleet:
replicas: 1
storage: { createClass: true, provisioner: ebs.csi.eks.amazonaws.com }
network:
internalFetchAllowlist: [".internal."] # intranet hosts agents may fetch for knowledge ingest
redis: { endpoint: , clusterMode: true, auth: { username: } }
redis: { mode: external }
postgres: { mode: external, external: { host: , port: 5432 } }
supabase:
ingress: { enabled: true, className: alb, host: auth., annotations: { ... } }
auth: { apiExternalUrl: https://auth., siteUrl: https://app. }
storage:
backend: s3
s3: { bucket: , region: }
serviceAccountName: storage-api
publicUrl: https://auth.
edgeRuntime:
publicUrl: https://auth.
functionsEnv:
APP_URL: https://app.
INBOUND_GW_URL: https://hooks.
AGENT_CONTAINER_INGRESS_DOMAIN:
DEPLOYMENT_MANAGER_PUBLIC_URL: https://dm.internal.
ui:
ingress: { host: app., className: alb }
authProviders: [sso]
env:
VITE_WEBHOOK_URL: https://hooks. # the app's baked default is the cloud host
VITE_EMAIL_DOMAIN: agents.
VITE_PLATFORM_URL: https://app.
VITE_SUPABASE_URL: https://auth.
VITE_AGENTS_API_URL: https://api.
VITE_CHAT_BACKEND_URL: https://chat./chat-backend/{agent_id}
VITE_ACTIONS_SERVICE_URL: https://actions.
VITE_CLIENT_AUTH_URL: https://client-auth.
VITE_LICENSE_MODE: "true"
VITE_OMNI_MCP_URL: ""
extraEnv:
- name: VITE_SUPABASE_ANON_KEY
valueFrom: { secretKeyRef: { name: xpander-generated-keys, key: SUPABASE_ANON_KEY } }
client-auth: { ingress: { host: client-auth. }, env: { APP_URL: https://app., CLIENT_AUTH_EXTERNAL_URL: https://client-auth. } } # the second turns on MCP OAuth
api:
ingress: { host: api. }
env: { API_URL: https://api., INBOUND_EMAIL_REPLY_DOMAIN: agents., SMTP_HOST: ..., SMTP_PORT: "587", SMTP_STARTTLS: "true", SMTP_USERNAME: ... }
extraEnv: [SMTP_PASSWORD, INBOUND_EMAIL_TOKEN, MAILGUN_SIGNING_KEY] # each from a Secret
agent-controller: { ingress: { host: chat. } }
webhook: { ingress: { host: hooks. } }
functions: { ingress: { host: links. } }
deployment-manager: { ingress: { host: dm.internal., className: alb-internal } }
actions:
ingress: { host: actions. }
env: { XPANDER_SANDBOX_DNS: }
catalog: { env: { OAS_GEN_BUCKET_NAME: , AWS_DEFAULT_REGION: } }
openapi-spec-generator: { env: { OAS_GEN_BUCKET_NAME: , AWS_DEFAULT_REGION: } }
```
Do not repeat the installer's own keys (`orgSeed`, generated passwords, image pins) in this file: extra values files merge last and would silently override what the installer computes.
### CI/CD & GitOps
The pattern has four steps. Fetch the release manifest once. Mirror its image set with credentials from the CI secret store. Re-run the install with that same file, your values and the license flags ([declarative re-install](#declarative-re-install-for-ci)). Gate on `status`. Run it on an agent with cluster access, Helm 3.13 or later, skopeo, and Python 3.
```groovy theme={"dark"}
pipeline {
agent { label 'xpander-admin' } // has kubectl access to the cluster
triggers { cron('H 6 * * 1') } // or trigger from releases.atom
environment {
XPANDER_PULL = credentials('xpander-pull-token') // username: xpanderaihub, password: the read token
XPANDER_ORG = credentials('xpander-org-id') // the organization id from the license handoff
}
stages {
stage('Mirror the release') {
steps {
sh '''
curl -fsSLO https://charts.xpander.ai/image_sync.sh
curl -fsSL https://github.com/xpander-ai/releases/releases/download/latest/release-manifest.json -o release-manifest.json
bash image_sync.sh --source docker.io/xpanderaihub \
--dest registry.corp.example:5000/xpander \
--release-manifest ./release-manifest.json \
--source-user "$XPANDER_PULL_USR" --source-token "$XPANDER_PULL_PSW"
'''
}
}
stage('Upgrade and verify') {
steps {
sh '''
curl -fsSL https://charts.xpander.ai/install.sh -o install.sh
bash install.sh --non-interactive --quiet --edition airgap \
--org "$XPANDER_ORG" --install-license-file install.json --activation-license-file activation.json \
--registry registry.corp.example:5000/xpander --mirror skip \
--release-manifest ./release-manifest.json --values values.yaml \
--helm-timeout 20m
bash install.sh status --quiet
'''
}
}
}
}
```
Exit codes do the gating (the [table above](#automation--ci)). The install step fails the build on three codes. Exit code `1` means the upgrade failed; a run against a deployed release adds `--atomic`, so Helm has already rolled it back. Exit code `2` is a usage error in the command line. Exit code `4` means a preflight check failed.
The `status` command fails on two codes. Exit code `1` means the install is degraded, and the output lists the reasons. Exit code `3` means nothing is installed.
`status --json` emits one JSON object if you'd rather parse than gate on the exit code.
The air-gap chart is standard Helm OCI. [Mirror it next to the images](#sealed--manual-mirroring), keep your configuration and generated release values in Git, and point an Application at both. Chart versions and image versions are separate: selecting a newer chart alone does not fetch the release manifest.
Generate the Helm values with the manifest-aware installer using your usual install arguments plus `--release-manifest ./release-manifest.json --values-out xpander/values.yaml`. It exports `xpander/values.yaml` and `xpander/values.yaml.release.json`. The second file contains Helm values, not the original release metadata. Keep the original manifest for your release record and pass both generated values files, with release values last:
```bash theme={"dark"}
helm upgrade --install xpander ./xpander-airgap-.tgz \
--namespace xpander --create-namespace \
-f xpander/values.yaml -f xpander/values.yaml.release.json
```
For Argo CD:
```yaml theme={"dark"}
apiVersion: argoproj.io/v1alpha1
kind: Application
metadata:
name: xpander
namespace: argocd
spec:
project: default
destination:
server: https://kubernetes.default.svc
namespace: xpander
sources:
- repoURL: registry.corp.example:5000/xpander/charts # OCI repo credential with "Enable OCI"
chart: xpander-airgap
targetRevision: # keep it in step with the release values
helm:
valueFiles:
- $values/xpander/values.yaml # generated once: install.sh --values-out
- $values/xpander/values.yaml.release.json # generated release image pins, applied last
- repoURL: https://git.corp.example/platform/xpander-config.git
targetRevision: main
ref: values
syncPolicy:
syncOptions:
- CreateNamespace=true
```
* **Values**: regenerate the release values for each release and review them together with the chart version. Do not add image overrides after the release values; direct Helm/GitOps does not enforce the installer's manifest checks. The generated file can carry secrets (LLM keys, external DSNs): strip those into your secret manager before committing.
* **Bootstrap secrets**: the `xpander-license` Secret (and the registry pull secret, when one is needed) are created once out-of-band (`kubectl create secret ...` as shown in [The License](#the-license)), or managed via SealedSecrets / External Secrets Operator.
* **Hooks**: Argo CD maps Helm hooks (the chart's preflight → keygen → migrations → org-seed → smoke pipeline) onto its own sync phases, and hook weights onto sync waves. This mapping is supported by Argo, but we have not certified the chart under Argo CD: **verify the hook ordering on your Argo version** before relying on it for upgrades; `install.sh` remains the certified path.
***
## Troubleshooting
Every installer failure prints two lines: **`FIX:`**, the action that repairs the condition, and **`RERUN:`**, your personalized non-interactive one-liner (secrets typed at prompts are shown as placeholders). The installer is idempotent: fix the condition, paste the rerun line, and it picks up where the failure left off. The air-gap checklist verifies preconditions before anything changes, so most problems stop the run with nothing to clean up. For scripted runs, the exit code names the failure class ([Automation & CI](#automation--ci)), and `bash install.sh status` gives a read-only health verdict.
### Mirroring and Registries
**Symptom:**
```
writing blob: initiating layer upload to /v2/xpander/ai-gateway/blobs/uploads/ in
123456789012.dkr.ecr.eu-west-2.amazonaws.com: name unknown: The repository with
name 'xpander/ai-gateway' does not exist in the registry with id '123456789012'
```
**Cause:** ECR refuses a push to a repository that does not exist yet, and there is no push-time flag to create one.
**Fix:** the current `image_sync.sh` creates each ECR repository automatically before pushing (it needs AWS CLI credentials on the machine running it). Refresh your copy:
```bash theme={"dark"}
curl -fsSLO https://charts.xpander.ai/image_sync.sh
```
On an older copy, pre-create the repository and re-run (already-landed copies are skipped fast):
```bash theme={"dark"}
aws ecr create-repository --repository-name xpander/ai-gateway --region
```
**Symptom:** `authentication required` writing to your registry, even though `docker login` to it succeeds.
**Cause:** `skopeo` cannot read logins kept in Docker Desktop's credential store, so the docker login is invisible to the copy.
**Fix:** the current `image_sync.sh` logs in itself for ECR destinations (`aws ecr get-login-password | skopeo login --username AWS --password-stdin`). For other registries, pass the credentials explicitly:
```bash theme={"dark"}
bash image_sync.sh --source docker.io/xpanderaihub --dest / \
--dest-user --dest-token
```
**Symptom:** `401 from auth.docker.io (incorrect username or password)`. The installer surfaces the registry's own reason.
**Cause:** the pull credential is the **organization username** `xpanderaihub` plus the read token from your delivery email. A personal Docker Hub username returns 401, and so does a token missing its read scopes.
**Fix:** re-run with the exact pair from the email (`--xpander-registry-user xpanderaihub --xpander-registry-token `). If it still refuses, ask xpander to re-issue the token: it needs repository-read and image-pull access to the gated repos.
**Symptom:** pod events show `manifest unknown`, or the installer's checklist reports:
```
✗ deployment-manager:0.0.417 not found in registry.example:5000/xpander
```
**Cause:** the mirror does not hold that repository at the pinned tag. A partial mirror, or an upgrade that pinned newer versions than were copied. Tags differ **per image** (each service versions independently), so one stale repo is enough.
**Fix:** re-run the mirroring for the release ([in-wizard](#when-the-mirror-is-empty-the-wizard-offers-to-fill-it), or `image_sync.sh`, safe to re-run), then verify the exact coordinate before retrying:
```bash theme={"dark"}
crane digest registry.example:5000/xpander/deployment-manager:0.0.417
```
### Cluster and Network
**Symptom:**
```
failed to pull image "docker.io/...": dial tcp 44.208.254.194:443: i/o timeout
```
**Cause:** a sealed cluster has no route to Docker Hub, which is expected. Some image reference is still pointing at `docker.io` instead of your mirror.
**Fix:** install with `--registry /` so every xpander image resolves in-network. Make sure the mirror itself is reachable from the **nodes**. On an ECR-only sealed VPC, that means the `ecr.api` + `ecr.dkr` interface endpoints, the S3 gateway endpoint, and ECR read on the node role. Find the offending reference with:
```bash theme={"dark"}
kubectl -n xpander get pods -o jsonpath='{range .items[*]}{.metadata.name}{"\t"}{.spec.containers[*].image}{"\n"}{end}' | grep docker.io
```
**Symptom:**
```
✗ no node with a supported architecture: cluster has [arm64], the images need [amd64]
```
(Or, past preflight on a mixed cluster: pods crash with `exec format error`.)
**Cause:** xpander images are amd64-only; ARM/Graviton nodes (`t4g`, `m7g`, `c7g`, ...) cannot run them. The installer's preflight and the chart's preflight hook both check before anything deploys.
**Fix:** add an amd64 node group (x86 instance types) and re-run. Only if you have genuinely arm64 images should you override the chart's check: `--set 'preflight.allowedArchitectures[0]=arm64'`.
**Symptom:** the ingress controller's Service never gets an address; its events show:
```
could not find any suitable subnets for creating the ELB
```
**Cause:** in a sealed VPC there are no public subnets, and the private subnets are missing the ELB role tags, so AWS has nowhere to put the load balancer.
**Fix:** for an internal load balancer, tag the private subnets and annotate the Service:
```bash theme={"dark"}
aws ec2 create-tags --resources \
--tags Key=kubernetes.io/role/internal-elb,Value=1
```
```yaml theme={"dark"}
metadata:
annotations:
service.beta.kubernetes.io/aws-load-balancer-internal: "true"
```
Or skip the load balancer entirely: reach the UI over your VPN, or with `kubectl -n xpander port-forward svc/ui 8080:80`.
**Symptom:**
```
Error from server (NotFound): namespaces "xpander" not found
```
**Cause:** the connectivity probe pod was launched before the install had created the namespace. Fixed in current installer versions.
**Fix:** refresh your installer copy (`curl -fsSL https://charts.xpander.ai/install.sh`), or create the namespace and re-run:
```bash theme={"dark"}
kubectl create namespace xpander
```
**Symptom:** data-tier pods stay `Pending`; `kubectl -n xpander describe pvc` shows unbound claims.
**Cause:** no usable RWO StorageClass (or the wrong one), or the cluster is under capacity for the [footprint](#prerequisites).
**Fix:** `kubectl get storageclass`, pass `--storage-class ` if the default isn't right; check `kubectl -n xpander get events --sort-by=.lastTimestamp` for `FailedScheduling` and add nodes if capacity is the constraint.
**Symptom:** the UI serves but renders a blank page; the browser console shows:
```
Missing or invalid environment variables
```
**Cause:** Xpander Chat validates its runtime origins (Supabase, chat backend) at boot and refuses to start without them. Chart versions before **0.6.0** did not derive the UI's runtime config from the base domain.
**Fix:** upgrade with `bash install.sh upgrade` (chart ≥ 0.6.0 injects the config from `--domain`). Staying on an older chart, set the origins yourself via `ui.env` (`VITE_SUPABASE_URL`, `VITE_CHAT_BACKEND_URL`, ...) in your values.
**Symptom:** `chat.` opens, but sign-in or API calls fail, `supabase.` / `api.` don't resolve, or land on a default-backend 404.
**Cause:** the install publishes [one host per service](#domains-ingress--dns) (seven with the derived names), and only one got a DNS record (or an `/etc/hosts` entry).
**Fix:** create a wildcard record (`*.`) pointing at the ingress controller, or one record per host: `chat`, `api`, `agent-controller`, `supabase`, `webhook`, `client-auth`, `actions` with the derived names, or whatever you set in `.ingress.host`. Verify what the cluster actually publishes:
```bash theme={"dark"}
kubectl -n xpander get ingress
```
### Install and Upgrade
The installer refuses to install over a release in a stuck status, and `install.sh upgrade` requires `deployed`: operating on a stuck release would strand it. Recover first:
```bash theme={"dark"}
helm history xpander -n xpander
helm rollback xpander -n xpander # if a good revision exists
helm uninstall xpander -n xpander # first install that never converged
```
Then paste your `RERUN:` line. `pending-install` usually means an interrupted or timed-out first install: `helm uninstall` is the right recovery. The `xpander-generated-keys` Secret survives the uninstall (Job-created, not Helm-rendered), so a reinstall keeps the same keys.
The chart refuses to render against unpinned xpander images. Load a complete [latest release](#releases), mirror its images, and retry with that same manifest. For direct Helm, pass both generated values files, with the release values last. Do not repair a missing release by guessing a shared image tag.
The installer checks the license files before anything is deployed. On a current install it reads the two `xpander-license/v2` files, `license.json` and `activation.json`, and confirms they name the organization passed with `--org`. On a legacy install it reads the single v1 file, its expiry and its organization id. The chart's preflight hook repeats the check in the cluster, including the Ed25519 signature, and the deployment-manager service repeats it at boot. To see where a running install stands, call `GET /v1/license/status` on the API. It answers `valid`, `expiring`, `grace` or `expired`.
**Expired:** the installer warns `License expired on - preflight will refuse the install`. Get a renewed `activation.json` from the xpander.ai team (delivered over email), replace only that key in the Secret, and redeploy:
```bash theme={"dark"}
kubectl -n xpander create secret generic xpander-license \
--from-file=install.json=./install.json \
--from-file=activation.json=./activation-new.json \
--dry-run=client -o yaml | kubectl -n xpander apply -f -
```
On a running install, follow with `install.sh upgrade` by hand or your pipeline's re-install: license consumers carry a checksum annotation over the Secret, so the redeploy rolls them onto the new file. If you pass your own `--values`, keep the `--set global.license.installKey/activationKey/publicKey` flags on that command ([The License](#the-license)). A legacy v1 install swaps its single `license.json` key the same way.
The `agents` service could not assemble the agent, most often because the agent holds a connection to an API connector that never finished its pipeline (status `faulty`, no spec). Confirm in the `agents` pod log: a pydantic error on `ConnectedConnector.open_api_spec_id`. Recovery, from the Supabase database inside the cluster:
```sql theme={"dark"}
-- the connections of the faulty connector
update public.connector_organization set deleted_at = now()
where connector_id = '' and deleted_at is null;
-- take the connection id out of the agent's skill list
update public.ai_agents
set attached_tools = (select coalesce(jsonb_agg(t), '[]'::jsonb)
from jsonb_array_elements(attached_tools::jsonb) t
where t->>'id' <> '')::json
where id = '';
```
Reload the agent in every open browser tab before anyone saves its settings again: Xpander Chat saves the whole agent from memory, and a stale tab writes the dead connection back.
The installer already printed the failing Job's last 30 log lines. Dig deeper:
```bash theme={"dark"}
kubectl -n xpander logs job/ --tail=100
kubectl -n xpander describe job/
kubectl -n xpander get pods,jobs
kubectl -n xpander get events --sort-by=.lastTimestamp
```
The org-seed stage requires `--org-name` and `--admin-email` whenever the Supabase stack is on: the checklist catches this before install; a hand-driven `helm upgrade` that drops them fails at render time.
A values file that sets a username but leaves `password: ""` beside it **overrides the generated password with the empty string**. Helm merges the explicit empty value over the keygen Secret's. The installer warns when it sees this shape; the fix is to drop the empty `password:` key from your values file entirely (a key that is absent is preserved, a key that is `""` wins).
On releases older than the single-provider generator, the operation-clustering step needed an OpenAI key for embeddings. Without one, it fell back to simpler grouping. That fallback transiently reported the run as failed: the creation dialog stopped with *"The AI enrichment pipeline reported a failure"* even though the pipeline finished seconds later. Check the skills list before retrying: the skill typically completed and is usable. Current releases run the embeddings on the install's own provider, so the false failure is fixed. Upgrading resolves it.
The chart pins image tags per release, so upgrading before mirroring the new bundle leaves pods unable to pull (typically with [`manifest unknown`](#troubleshooting)). Re-run the mirroring for the target release, then re-run the upgrade: it runs with `--atomic`, so the failed attempt already rolled back and the previous revision kept serving.
`helm upgrade --reuse-values` replays the previous release's computed values, which can resurrect a stale edge-runtime placeholder image pin that newer chart versions removed. Upgrade with your real values files instead (what `install.sh upgrade` does), or clear the stale pin once:
```bash theme={"dark"}
--set supabase.edgeRuntime.image.repository=null --set supabase.edgeRuntime.image.tag=null
```
Better: pin the real mirrored edge-functions build (`--edge-functions-tag`).
The two self-hosted deployments share nothing and cannot be upgraded into each other. Install under a different release or namespace (`--release` / `--namespace`), or remove the existing release first (`helm uninstall xpander -n xpander`).
Piping into `bash` leaves no stdin to prompt on, so the run is non-interactive: Air-Gapped requires `--org`, `--install-license-file` and `--activation-license-file` (or `--license-file` on a legacy v1 install). Missing flags exit with code 2 and a completed rerun line. Download the script and run `bash install.sh --edition airgap` from a terminal for the interactive wizard.
***
## Next Steps
* [Air-Gapped Security Architecture](/resources/security-compliance/air-gapped-deployments): zero egress to xpander Cloud, signed Ed25519 license, local sign-in
* [Advanced: review-first / manual install](/self-hosted/hybrid#advanced-review-first--manual-install): read the installer before running it, plus `--manual`, `--values-out`, and `--dry-run`
* The chart's own README (inside the `.tgz`) covers advanced topics: bring-your-own ingress for the UI/API/Supabase gateway hosts, private CA and corporate proxy support, SMTP, internet posture and skill offering, builtin-skills seeding, and Bedrock region pinning
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.